Self-Hosted • Free • Open Source | Alteryx simplicity with Polars multi-threaded speed

Visual Data Pipeline Automation. Locally Hosted. Polars Fast.

Build and execute complex Directed Acyclic Graphs (DAGs) locally. Experience sub-millisecond execution times with multi-threaded Polars DataFrames, seamless Gemini Multimodal AI orchestration, and an embedded Python IDE.

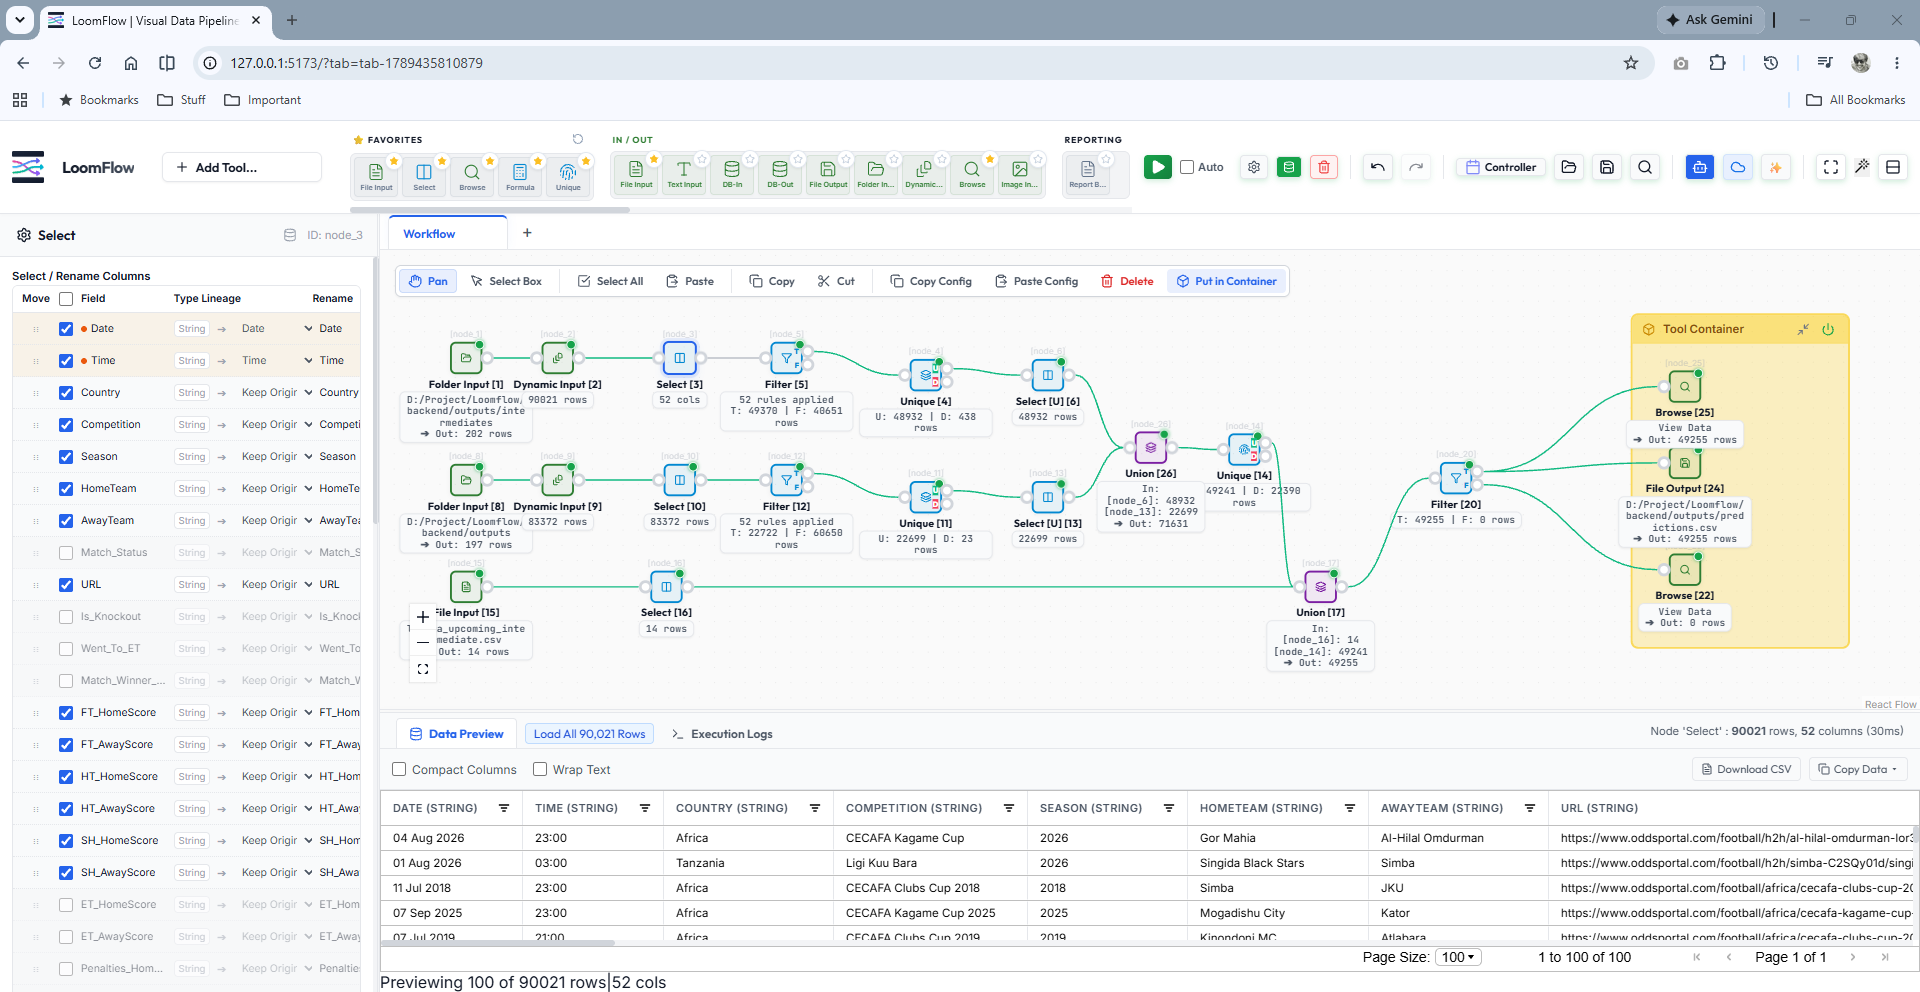
LoomFlow Visual Data Pipeline Workspace showing Select panel, DAG canvas with dynamic input, union, filter, tool containers, and data preview
Click to expand high-resolution UI preview

Architected with High-Performance Open Source Foundations

⚡ Polars Rust Engine
⚛️ React Flow Canvas DAG
🚀 FastAPI Async Python
✨ Gemini AI Multimodal
📦 Apache Parquet Fast Caching

Interface Architecture

Modeled for Analysts. Built for Engineers.

LoomFlow translates enterprise Alteryx workflows into modern open-source software, pairing visual clarity with high-speed execution.

Column Cast & Rename Inspector

Inspect column lineage in real-time. Dynamically cast strings to dates, rename headers, and prune unnecessary fields before feeding into heavy downstream calculations.

Select [Node 3]

Extensive Tool Ribbon

Alteryx-style tool categories: Favorites, In/Out, Preparation, Transform, Join, and Reporting. Drag Dynamic Inputs, Formulas, and Filters straight onto the canvas.

+ Add Tool / Shortcuts

Multi-Stream DAG & Containers

Group related operational branches inside Tool Containers. Seamlessly union parallel streams, apply complex multi-rule filters, and deduplicate with Unique nodes.

Tool Container [26, 27]

Instant Data Preview & Logs

Click any node to immediately view cached row profiles and schema types. Inspect 90,000+ rows in 30ms, copy tables to clipboard, or export direct to Parquet/CSV.

Load 90,021 Rows
Multi-Threaded Vectorized Execution

Stop Waiting on Legacy Pandas Workflows.

Standard Python ETL suites choke on memory limits and single-core bottlenecks. LoomFlow is built natively on Polars and Rust execution cores to ensure your workstation remains responsive even when crunching millions of rows.

✓ Vectorized query optimization with Apache Arrow
✓ Sub-millisecond branch pruning & disk caching
✓ Auto-recovery with zero data loss
BENCHMARK: 1M ROWS FILTER, JOIN & GROUP BY Faster is better
LoomFlow (Polars Engine) 0.032s (32ms)
Standard Python (Pandas) 1.840s (1,840ms)

Up to 57x faster execution on identical hardware.

Architectural Principles

The Four Pillars of Data Pipeline Confidence

Inspired by the proven governance principles of Alteryx ("VURA"), reimagined for modern open-source stacks.

👁️

Visible

Eliminate invisible Python script errors. Build explicit visual DAGs where upstream and downstream column lineage is traceable at every point.

🧩

Understandable

Self-documenting workflows allow analysts, data scientists, and business stakeholders to visually understand exact business logic at a glance.

🔁

Repeatable

Deterministic execution powered by in-memory Polars. Run the exact same pipeline locally across millions of records without environment drift.

🛡️

Auditable

Per-node row throughput counters, automated type inference logs, and intermediate Parquet snapshots provide full governance on your own PC.

Developer Quickstart

Up and Running in 60 Seconds

Run LoomFlow completely locally. Single script execution resolves virtual environments and dependencies automatically.

bash / powershell

# 1. Clone the repository

git clone https://github.com/cardchase/loomflow.git

cd loomflow

# 2. Run the automated setup script

.\run.ps1

# 3. Open your browser

→ http://localhost:5173

Prerequisites: Python 3.10+ & Node.js 18+ Automatic venv + dependency resolution
🚀 Product Hunt Launch Ready

Support LoomFlow on GitHub

LoomFlow is open source and community driven. Star the repository, report issues, and help us build the premier local-first alternative to proprietary ETL.

Copied to clipboard!